We crawl the website to identify issues associated with its URLs and files, then analyse and filter the results so developers and website owners can focus on the issues that matter. The service can be used as a one-off investigation or as ongoing technical monitoring.
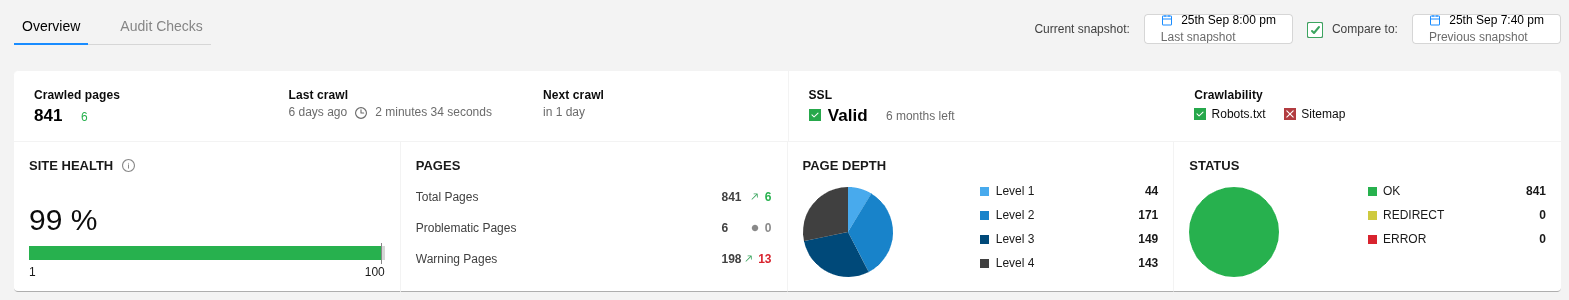
Technical crawling with the priorities already filtered
A crawler can export thousands of rows. Our role is to analyse that information, identify the material issues and organise the findings into work that can be understood and acted on.
Crawlability and indexability
Status codes, robots directives, canonical tags, XML sitemaps and other signals that affect how URLs can be discovered and indexed.
Website structure
Internal links, crawl depth, orphan pages, redirects, pagination and structural patterns that can create inefficiency or confusion.
Page and content signals
Metadata, headings, duplication, structured data, image issues and other URL-level elements visible through the crawl.
Developer-ready priorities
Prioritised issues, affected URLs, instructions and examples that give the development team a practical starting point.
Illustrative crawl map showing how groups of URLs and internal-link relationships can be explored during technical analysis.
One-off analysis or ongoing technical monitoring
Crawling Analysis can support a migration, a website change, an indexation problem, a large website or a specific technical investigation. It can also run on an ongoing basis so one crawl can be compared with the next and previously reported issues can be checked again.
Clear information for developers and website owners
Developers can receive a spreadsheet containing prioritised issues, affected URLs, implementation instructions and examples or screenshots where useful. The business owner or marketing lead can receive a clearer status update focused on the main issues and whether previously identified problems have been resolved.
CMS access is not required. Server or log information can be used where relevant. Pricing is based primarily on the number of URLs to be crawled and the complexity of the website.